How to Benchmark OCR Accuracy: CER, WER, and Workflow Risk
November 6, 2026
Key Takeaways:
Trustworthy CER and WER comparisons require representative held-out documents, independently verified references, and fi

Turn mixed, complex documents into structured, usable data. iTech combines AI-driven OCR, document classification, and validation workflows to help organizations extract the right fields, reduce manual review, and move information faster across downstream systems.

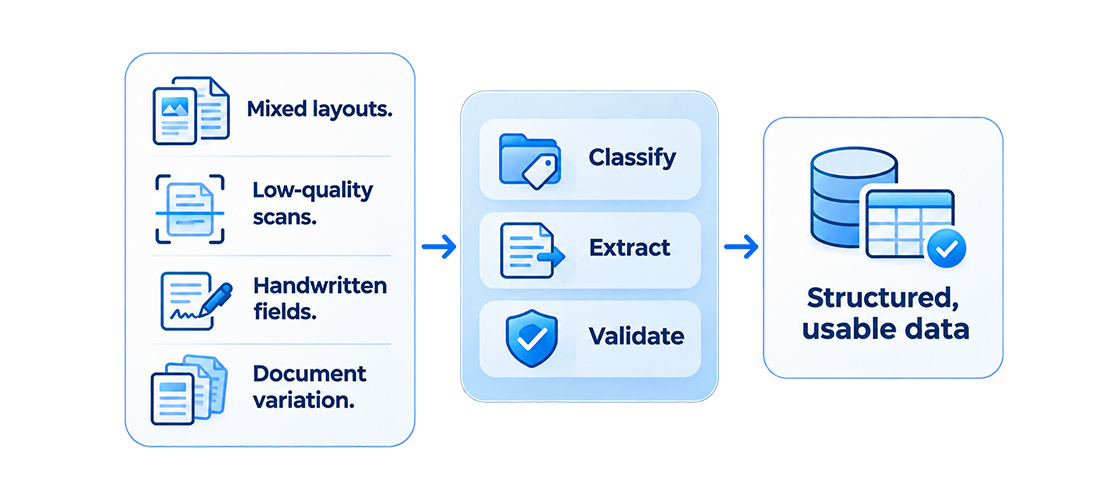
When teams rely on manual review to sort documents, identify fields, and rekey information, processing slows down fast. Mixed layouts, low-quality scans, handwritten fields, and document variation make it harder to capture the right data consistently.
iTech helps organizations reduce that burden with intelligent document processing that classifies files, extracts key fields, and supports cleaner downstream workflows.
Tell us about your document types, extraction needs, and workflow goals, and we’ll help map the right IDP and OCR approach.
Identify document types automatically so files move into the right workflow with less manual sorting.
Capture key information from invoices, forms, records, and other documents with greater speed and accuracy.
Minimize time spent checking every file by using rules, validation, and exception handling to support cleaner processing.
Turn document data into structured output that fits ERP, AP, logistics, healthcare, and other downstream systems.
Different files require different logic. iTech supports the key steps needed to turn incoming documents into usable structured data.
1
Identify document types automatically, even across mixed layouts and high-variation files, so each document can follow the right downstream path.
2
Capture key data from invoices, forms, records, blueprints, and other complex business documents using AI-driven OCR and document extraction workflows.
3
Apply business rules, review logic, and exception workflows to help improve quality before data is passed downstream.
A strong fit for teams handling mixed-format documents, semi-structured files, or high-volume extraction workflows where manual review is slowing things down.
Extract and structure data from bills of lading, freight invoices, packing lists, and related shipping documents.
Support data extraction from document-heavy administrative and claims-related workflows where speed and consistency matter.
Capture data from orders, technical documents, and varied operational records without relying on manual review alone.
Improve access to document data across legacy records and form-driven workflows.
Intelligent Document Processing and OCR is designed for organizations that need to classify incoming documents, extract key fields, and support workflow automation from mixed or complex files.
If your main challenge is converting paper archives into searchable digital records for storage, retrieval, and long-term access, that belongs under Document Scanning and Digitization instead.